A US appeals court upheld Thomson Reuters’ copyright victory against ROSS Intelligence, rejecting the legal-research company’s fair-use defense over its use of Westlaw material to train an AI
A US appeals court upheld Thomson Reuters’ copyright victory against ROSS Intelligence, rejecting the legal-research company’s fair-use defense over its use of Westlaw material to train an AI search engine, Reuters reported on September 29.
The outcome of the case could have implications that extend beyond the realm of legal research. In the event that AI firms are required to shell out more for the data they use in the training of their systems, then availability of high-quality proprietary content could turn into one more advantage of companies with big wallets.
The ruling that went further the second time around
On February 11, 2025, Judge Stephanos Bibas reviewed his previous decision in 2023 and upheld part of it, thus giving Thomson Reuters a victory in its claims of direct infringement and fair use.
ROSS had wanted a licensing agreement for the Westlaw content but was denied as it was in competition with Thomson Reuters. Later, it procured almost 25,000 “Bulk Memos” sourced from LegalEase, which were created on the basis of Westlaw headnotes. Judge Bibas indicated that the infringement was regarding 2,243 headnotes.
“Ross took the headnotes to make it easier to develop a competing legal research tool. So Ross’s use is not transformative.” — Judge Stephanos Bibas
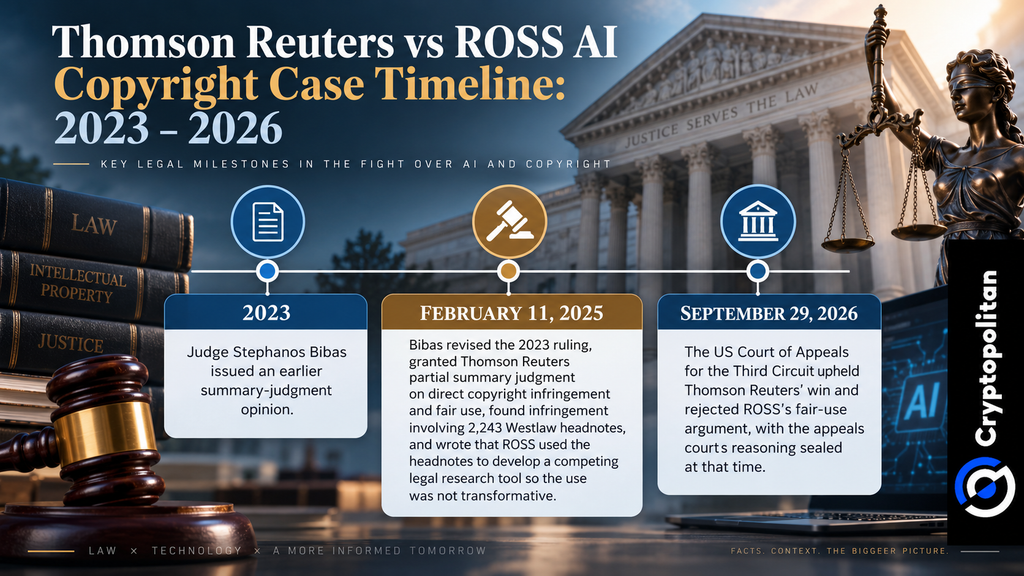
Thomson Reuters vs ROSS AI Copyright Case Timeline: 2023–2026
Why this is not a blanket ban on AI training
Understanding this distinction is important: ROSS has developed a legal search engine and not a generative large language model. Bibas clearly indicates that “only non-generative AI” is being considered by the court.
The US Copyright Office also believes that fair use is highly dependent on facts in the context of generative AI. Its analysis takes into account the material used, how it was obtained, the grounds for copying it, and how the use of said material affects the value of the original.
As a result, the decision made in ROSS is important but cannot be generalized to other AI training disputes.
Where the licensing bill lands
The Copyright Office supports the idea of the formation of voluntary licensing markets right before Congress moves to compulsory measures, while it also recognizes that licensing at AI-training scale can be quite costly and difficult to manage.
The financial burden may not fall evenly amongst companies. According to the OECD, having tight control over data, computing power, and other critical inputs gives the upper hand to the already prominent players.
The current extent of the market is incredible. According to Goldman Sachs, global investment in AI will be around $1 trillion by 2026, with $581 billion in the US alone.
Cryptopolitan has also reported on the copyright fight surrounding OpenAI and Microsoft, showing how licensing and fair use are becoming central business issues across the AI industry.
Two continents, two playbooks
The US is largely resolving these disputes through case-by-case fair-use litigation. Europe is building a different layer of infrastructure.
Under Article 4 of the 2019 DSM Directive, rightsholders can reserve works from text and data mining. In July 2026, the European Commission published a feasibility study for an EU-level registry that could help AI developers identify those opt-outs using fingerprints, identifiers and metadata.
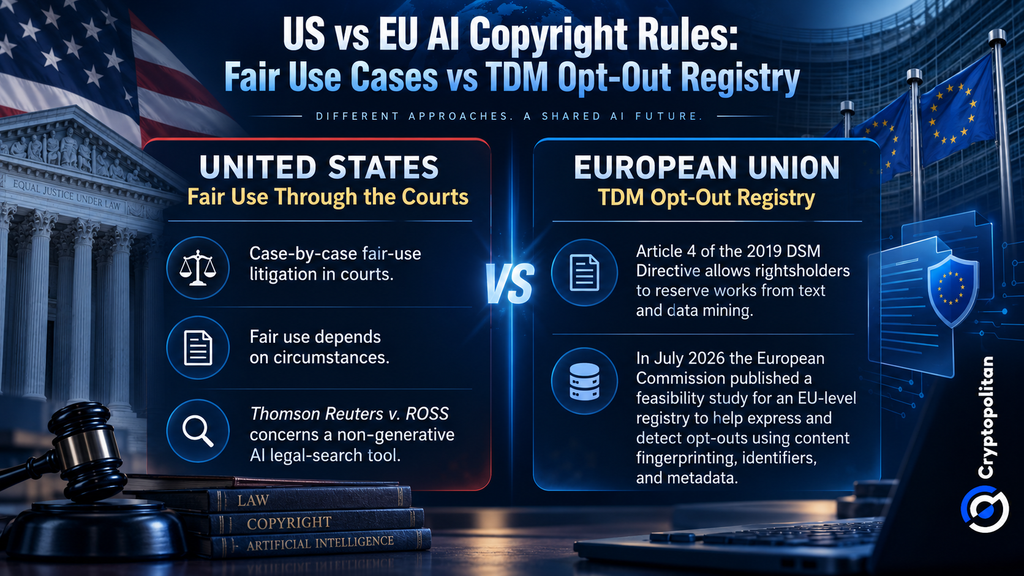
US vs EU AI Copyright Rules: Fair Use Cases vs TDM Opt-Out Registry
One system is being shaped in court. The other is trying to make rights reservations visible before training begins.
The smartest crypto minds already read our newsletter. Want in? Join them.